Ten Tickets or One: Running Our Agent Pipeline Lean
Our agent pipeline worked in small batches without cutting setup time, so even a tiny ticket used millions of tokens across its delivery cycle. What we measured moving from GitHub Projects to Milestones, what got worse, and the lean changes we make next.
By Patrick Heneise
We run three products with one agent pipeline and one human. Claude Code writes, reviews and ships the code. Codex reviews it too. In the last 18 days on our old setup, the pipeline merged 650 pull requests.
At the end of September we changed two things at once.
- GitHub Projects to Milestones. An issue used to sit on a Projects board and move from backlog to ready to in progress to done. Now it belongs to a milestone and is open or closed.
- Ten small tickets to one large one. We used to file one issue per small change and open one PR per issue. Now we file one package per outcome, with a definition of done, and it takes as many PRs as it needs.
Both changes trace back to a lean idea we had applied halfway. The Toyota production system, which lean startup borrows from, runs small batches. Toyota could afford them because it cut setup time, the time it takes to switch a line from one part to the next. Our pipeline had the small batches and kept the long setups.
Every ticket an agent pipeline picks up brings coordination work: scope it, classify and label it, pick it from the queue, load context and track its status. Then come implementation, review, fixes and acceptance. On our board, the median ticket under 100 lines used 4.8M tokens across that whole cycle. Our bet is that one package repeats less of that coordination than ten tickets that serve the same outcome.
What we found: in our data, large tickets cost far fewer tokens per line than small ones. After the switch, tokens per merged PR fell by about 15%. Our first version on Milestones also ran the full review stack on every PR, and review sessions per PR rose from 0.8 to 2.6.
What the numbers measure. Every figure is a token count from local Claude Code transcripts. Cache reads count at full size, so the totals measure token volume, not dollars or elapsed time. Cached input is priced differently from fresh input and output. Session totals are measured. The overhead categories, the per-ticket fit and the scenarios without board helpers are estimates. The comparison of small and large tickets is an association across different tickets, not an experiment. The Method section at the end has the details.
What one ticket costs
A ticket in our pipeline is not one agent call. It is a chain of agent sessions:
- A runner picks the next ticket and dispatches it.
- A builder reads the issue and the repo’s instructions, writes the change and opens a PR.
- Reviewers check the PR: code review, a simplify pass, a security review when the diff touches the server, a legal review when it touches user-facing claims.
- Fix rounds address what the reviewers found.
- The PR merges and the ticket closes.
Each session starts with its own context: the system prompt, the tool definitions, the repo’s agent instructions and the dispatch prompt. The median dispatch on the board started with 55,000 tokens and ran 24 turns. Every later turn reads the prior context again until compaction trims it. Across the board era, a merged PR took 5.6 sessions.
Part of that cost recurs whatever the size of the change, though complexity also drives session counts and review effort. A 13-line copy fix on an about page ran three sessions and used 7.8M tokens. A 47-line fix that hid one form section ran four sessions and used 7.6M.
A straight-line fit of the attributed board-era tickets’ tokens against their lines changed gives an intercept of about 13M tokens per ticket, plus about 9,300 tokens per line. Read the intercept as the estimated size-independent part of a ticket’s whole cycle. It does not measure tokens spent before coding. A few expensive tickets pull it up: the median ticket under 100 lines used 4.8M in total. Both figures point at recurring coordination. Neither isolates its cost.
The lean name for this is setup time. Shigeo Shingo’s single-minute exchange of die cut Toyota’s die changes from hours to minutes, so a press could run a small batch without losing the day to the changeover. Booting an agent session is our changeover. Carrying context through later turns is closer to a running cost, and the analogy does not cover it.
Ten small tickets or one large one
Picture one feature filed two ways: ten separate issues, or one package with ten implementation steps. Ten is illustrative. Both deliver the same behavior and must pass the same acceptance checks. It is the difference between independently dispatched issues and one coordinated package, like issues grouped under an epic.
| Activity | Many separate issues | One coordinated package |
|---|---|---|
| Describe the work | Shared outcome plus a description per issue | Shared outcome plus implementation steps |
| Classify, label and prioritize | Repeated per issue | Primarily per package |
| Select work and track status | Queue selection and status changes per issue | Package selection plus internal progress tracking |
| Load shared context | Repeated across independent sessions | Reused where the same session can continue |
| Implement, test and review | Required for the same feature | Required for the same feature |
| Accept the complete outcome | Required | Required |
The package should remove repeated administration and context loading. It still needs coordination inside. An epic saves nothing if each child issue runs the same independent pipeline as before.
We have not run that experiment. What we have is the board era’s tickets sorted by size. The table below multiplies the median small ticket (150 to 500 lines changed) by ten and sets it beside the median large ticket (more than 1,500 lines). These are different tickets, not one feature delivered two ways:
| 10 × median small ticket | Median large ticket | |
|---|---|---|
| Lines changed | 2,780 | 4,338 |
| Agent sessions | 50 | 15 |
| Estimated overhead tokens | 37M | 11M |
| Total tokens | 78M | 26M |
| Tokens per 1,000 lines changed | 28M | 6M |
The median large ticket changed 56% more code with a third of the tokens. Task type, complexity and retries may differ between the groups, and lines changed measure diff volume, not delivered value. So the table does not prove a 52M-token saving for equivalent work. It is why we think the package bet is worth testing.
Under our allocation, context loading is almost all of the estimated overhead: 7.2M of 7.5M tokens per merged PR on the board. A large ticket used 15 sessions to a small ticket’s 5: more, but not ten times as many. We have not yet tested whether coordinating the same work as one package reproduces that gap.
Keep commits small, let PRs grow
In our pipeline, agents do the routine PR review. Nobody reads each PR end to end as the normal gate, so we lose the reason to size every PR for one human sitting. A PR can cover a coherent package while its commits stay small and each one describes a single change.
Keep those commits intact when merging, and link each one to the issue or implementation step it serves. A change can then be found and cherry-picked without the whole PR, as long as its dependencies come with it. Small commits are not automatically independent: a database change and the code that depends on it may need to travel together. Code and commit messages still have to make sense to whoever debugs them later.
We coordinate by package and change by commit. One package can hold several commits and, when release risk or integration calls for it, several PRs. Larger PRs still pass code review and checks. We have not shown that agent review quality holds as diffs grow.
Bigger diffs are not the goal. Less repeated setup is. Grouping related steps is one way to test that, and loading less context and keeping it across those steps is another.
Why we had small tickets
GitHub Projects was great while it lasted
Projects solved a real problem. It gave one view across many repos, with a status per card. We used it for years. Milestones have been part of GitHub Issues since 2011, but a milestone lives in one repo, and we worked in polyrepos, with api, dashboard, infrastructure and marketing-website each in their own. A release that touched all four needed four milestones with nothing tying them together. Projects was the cross-repo view, so Projects won.
That separation was a human one. It let four people, or four teams, work without stepping on each other. For our workflow, we chose to bring those components into one repo per product, so an agent can work across the API, dashboard and site in one branch. That is our repository choice. It is not a reason for every team that uses agents to give up separate repos.
A board is a human interface
A Projects board answers one question: what is everyone working on right now? That matters when people work on tickets for days and other people need to know where things stand.
Our pipeline does not work like that. By the time a card says “In progress”, the PR is often merged. Nobody, human or agent, made a decision based on that column.
Status is also not one value. A ticket can sit on a development board, a marketing board and a board for one epic at the same time, with a different status on each. We ran two boards per product. The development board had four columns plus Priority and Effort fields. The marketing board had six statuses and three more fields. Every status change had to carry a comment on the issue saying what changed and why.
We also rewarded small cards in how we used the board. A card that moves across the board every day looks like progress. A card that sits in “In progress” for three days looks stuck. We cut work into tickets a human could review in one sitting and watch move, and the pipeline inherited that shape.
Lean calls this a vanity metric: a number that looks good and drives no decision. Cards moved and PRs merged both went up as tickets got smaller. Neither told us what a feature cost.
What the board cost
GitHub Projects has no simple status field an agent can set. A status is a single-select field on a project item, and setting it takes a GraphQL mutation with the project’s and the item’s node IDs, the field’s ID and the option’s ID. We had Claude write helper scripts so agents could use the boards:
| Tooling | Lines when removed |
|---|---|
| Development board helper (move, triage, priority, effort, reorder, snapshot and 8 more subcommands) | 484 |
| Marketing board helper | 679 |
| Triage helper | 48 |
| Board config and field constants (docs the agents read) | 712 |
| Total | 1,923 |
These files took 29 commits in three weeks. The commit that removed them deleted 5,073 lines, including tests.
Board calls over the last 18 days, with their estimated token attribution, across the projects described in Method:
| Board call | Calls | Estimated attributed tokens |
|---|---|---|
| Raw API calls, bypassing the helpers | 409 | 8.8M |
| Set fields, triage, reorder | 306 | 2.1M |
| Read board state (list, snapshot, show) | 274 | 13.6M |
| Move a card to a new status | 227 | 4.6M |
| Marketing board | 242 | 6.5M |
| Status comments and other helper calls | 246 | 9.3M |
| Total | 1,704 | 44.9M |
The allocation puts a card’s three status moves and their comments at about 60,000 tokens. Seven sessions that built and fixed the board scripts used another 115M tokens. That counts whole sessions; the 44.9M above is an estimated attribution per call, so the two are not directly comparable.
Without the helpers
The helpers hid most of the API. One status move was three GraphQL calls: look up the card’s item ID, set the field, and read the status back to confirm the move landed. Reading a column paged through every card on the board, 100 at a time, and cut the JSON down to number, title and labels before the agent saw it. All node, field and option IDs came from a config file.
An agent working the API directly pays for each of those steps. Every extra call is another turn, and every turn reads the session’s context again. In sessions that touched the board, the median turn read 113,000 tokens. Raw board JSON is also long, and a column read without a filter can fill the shell’s output limit before the agent filters and asks again.
We did not run the pipeline without the helpers, so these are estimates from the same sessions, not measurements:
| Board access | Estimated tokens, 18 days |
|---|---|
| Observed calls, including helpers and raw API calls | 44.9M |
| Raw API, batched scenario: IDs in instructions, the three calls of a move chained in one command, every read filtered | about 58M |
| Raw API, separate-turn scenario: one call per turn, IDs looked up once per session, the first read of a column unfiltered | about 310M |
We have not measured which scenario an agent would follow, so the saving the helpers caused is unknown. Their bigger job was keeping unattended runs from stalling. Inline GraphQL trips Claude Code’s shell permission check, and a call that waits for approval stops a run nobody is watching.
The board itself was not the big cost. The three products alone merged 650 PRs in those 18 days, while the helpers recorded 227 status moves across all projects, and a quarter of the board calls went around the helpers straight to the API. The estimated 44.9M tokens of board calls are small next to the context-loading totals, though the two are scoped differently. Our main suspect is the repeated coordination around small tickets. Projects did not require that ticket size. Our workflow did.
How we work now
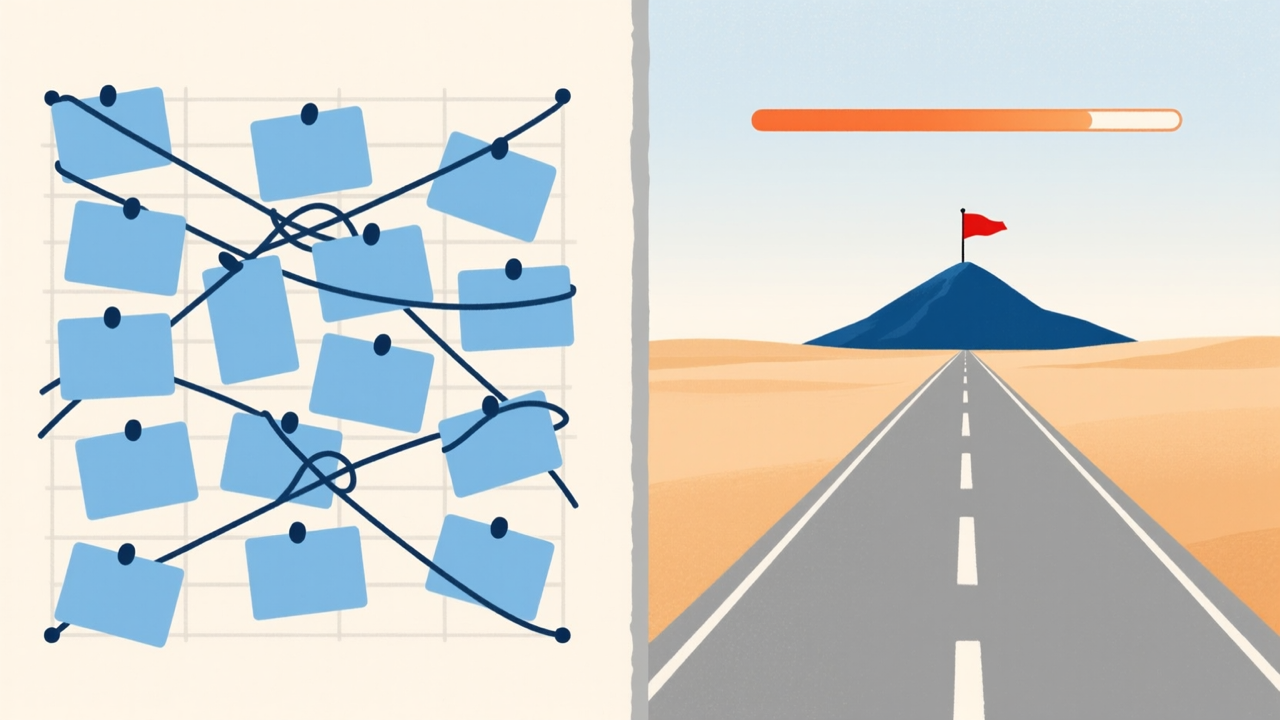
A milestone is a dated outcome. For example: “A new customer can sign up, pay and use the product without help”. It has no status column. Its issues are open or closed, and the milestone shows how many of each. It uses the REST API with plain issue numbers instead of GraphQL node IDs. We use it to record a change in what users can do, with a date to check it by. A milestone alone is not a hypothesis: we still need a prediction and a measure of the outcome.
A package is one issue per outcome inside a milestone. It holds what a builder needs to finish without coming back to ask:
## Outcome
What is true for the user when this is done.

## Definition of done
- Each check a reviewer can verify against the running product.

## Evidence
What the final PR or the acceptance step must show: tests, screenshots, a query.

## Out of scope
What a builder should not touch, so the package does not grow.
This is the shape Addy Osmani’s notes on getting the most out of Opus 5.5 ask for: give the whole task in one message, name the finish line and let it work. The companion post on building with Sonnet 5.5 puts well-scoped everyday tasks on Sonnet and long-horizon work on Opus. Both support giving the agent a complete outcome. Neither says how big an issue or a PR should be.
A package closes through acceptance, not through a PR. It may take several PRs. When the definition of done is met, an acceptance step checks the evidence and closes the package. In the last board week (Sep 23 to 29), GitHub linked 208 closed issues to the PR that closed them. In the first Milestones week (Sep 30 to Oct 6) it linked 12, by design.
The backlog gets consolidated. Instead of loading context for a few hundred open issues, an agent loads a dozen packages. Every inbound ticket is either absorbed into a package or parked as an idea. Across the three products, from September 29 to October 6:
| Count | |
|---|---|
| Issues closed | 334 |
| Absorbed into a package | 116 |
| Parked as an idea | 159 |
| Closed by a PR, per the last comment | 11 |
| Other closes | 48 |
| Packages filed | 68 |
| Packages with merged PRs so far | 50 |
Open issues across the three products fell from 261 to 109 in the first week, and new issues filed per week fell from 383 to 160.
Packages are bigger than the issues they replaced. Measured on those 50 packages, against the 470 single issues closed through a PR in the board era:
| Single issue (Projects) | Package (Milestones) | |
|---|---|---|
| Lines changed, median | 305 | 512 |
| Lines changed, 75th percentile | 832 | 1,465 |
| PRs per unit, median | 1 | 2 |
| Units with more than one PR | 2% | 54% |
What the first 11 days show
Tokens per merged PR across the three products, for the last 18 days on the board and the first 11 on Milestones. Totals come from the transcripts. The overhead rows are estimated allocations, and Work is what remains.
| Tokens per merged PR | Projects | Milestones |
|---|---|---|
| Context loading | 7.2M | 7.3M |
| Issue reads | 0.22M | 0.50M |
| Board calls | 0.07M | 0.02M |
| Package queue and milestone calls | 0 | 0.37M |
| Overhead | 7.5M | 8.2M |
| Work | 13.3M | 9.4M |
| Total | 20.8M | 17.6M |
Tokens per merged PR fell by about 15%. A before-and-after comparison cannot separate the effects of the tracker, the package size and the review policy. The same fit as above puts the size-independent part at 9.5M tokens per ticket, down from 13M. Sessions got shorter: a median of 14 turns instead of 24, starting from 46,000 tokens of context instead of 55,000.
That is a smaller gain than the ten-to-one picture suggests, because the first version also added costs of its own:
- Packages split into PRs, and every PR ran the full review stack. The median package took 2 PRs, and review sessions per PR went from 0.8 to 2.6. A merged PR took 7.5 sessions instead of 5.6. A large package had a median of 34 sessions and 64M tokens, more than twice a large ticket on the board. One package shipped as five PRs over 60 sessions.
- The queue costs more than the board did. It made 2,283 calls in 11 days to select packages, record progress, label and accept: 0.37M tokens per PR against the board’s 0.07M. Part of that was the tests and fixes of a tool still being built.
- The first week went into consolidation. 275 issues were absorbed or parked, and the pipeline spent part of the week working on itself (below).
Our bet concerns how work is coordinated, not which tracker stores it. Projects can hold outcome-sized packages too. If each PR inside a package starts fresh builder and reviewer sessions, most of the repeated context loading stays. Moving to Milestones did not change that by itself.
Some of the repeated review is duplicate work. Some of it catches defects before they spread, which is what lean’s jidoka means by exposing errors early. So we will not push all code review to final acceptance. We will test reusing context across related changes and dropping checks that run twice, while each change keeps the checks it needs. Review counts alone cannot tell us whether quality held.
We also made the switch the way lean warns against. Moving to Milestones was a pivot, and we wrote down no prediction of what it would change. We only saw how far review activity had grown when this analysis ran, 11 days later.
What Milestones do not fix
A milestone says where to go. It does not make the agents go there. After one week we had to step in and correct the direction.
PR titles start with a conventional-commit type, so the mix shows what kind of work merged:
| Product | Week | feat | fix | docs + chore |
|---|---|---|---|---|
| A | Projects | 14% | 34% | 25% |
| A | Milestones | 11% | 27% | 57% |
| B | Projects | 27% | 36% | 27% |
| B | Milestones | 12% | 39% | 49% |
| C | Projects | 23% | 5% | 59% |
| C | Milestones | 32% | 12% | 54% |
In all three products, about half or more of what merged in the first Milestones week was docs and chores. In A and B, features fell to 11-12%. A type prefix shows the kind of work, not its value. The low feature share made us look at the work itself. The prefixes alone cannot say whether the pipeline was working on itself or doing useful maintenance.
From the correction on October 5 through October 10, the mix moved. In product A, features rose to 24% and docs plus chores fell to 43%. Product B shifted toward fixes: 42%, with docs and chores down to 47%. The median merged PR grew from 129 lines to 286, and the share over 500 lines from 26% to 35%.
Lean separates output from validated learning: what shipped, and what it changed for the people using it. Even the corrected mix measures output. None of these numbers say whether a user can now do something they could not. The acceptance step checks the definition of done. Nothing yet checks the milestone’s outcome after the package closes.
What we change next
Each change below runs as a build-measure-learn loop. It starts from a recorded baseline and makes one change. The prediction is written down before the change ships, and the same number is checked a week later.
Cut setup time
Sessions start from a median of 46,000 tokens of context, carried into later turns until compaction trims it. Load less per role, and keep one builder through a whole package instead of booting a new one per PR. Prediction: the fitted size-independent part falls below the current 9.5M tokens. We will compare similar task types and report how uncertain the fit is, because a lower intercept alone does not prove less coordination.
Remove duplicate review
The median package takes 2 PRs, and each PR gets 2.6 review sessions. Test carrying review context across related changes and keeping the check of the complete outcome for package acceptance. Keep pre-merge code review and security checks where the change needs them. Prediction: review sessions per accepted package fall with no rise in escaped defects, reverts or corrective work. A lower review count alone is not success.
Count the pipeline every week
Report tokens and sessions per accepted package, the fitted size-independent part and review sessions per package every week, next to escaped defects, reverts and corrective work. PR and issue counts stay as denominators, not success metrics. Tokens per changed line can describe a sample, but as a target it would reward writing more code.
Write the prediction first
Every change to the pipeline names the number it should move, and by how much, before it ships. With a written prediction and a weekly report, the review cost of the Milestones switch would have shown up as a miss in the first week instead of 11 days later in an analysis.
Check the outcome after acceptance
A week after a package closes, check the milestone’s user metric and record whether it moved.
Where lean stops fitting
We have not calculated the sample size needed to tell two pipeline setups apart. The first eight days produced 50 packages with merged PRs across three products, not 50 equivalent, accepted outcomes. Weekly before-and-after comparisons are practical for us, but changes in task mix, models and tooling can explain the differences. They can guide the next test. They cannot prove cause.
For developers and project managers
- Measure the whole delivery cycle. Sum the sessions you can tie to each ticket and report what you cannot. Keep observed totals apart from estimated overhead. Our small tickets used millions of tokens in total; we did not measure millions spent before coding.
- Cut setup time before you grow the batch. Coordinating related steps as one package may avoid repeated setup. A smaller starting context cuts token volume for small and large tickets alike.
- Write one ticket per outcome. Give it a definition of done a reviewer can check and the evidence it has to show. If ten tickets add up to one feature, file the feature.
- Size PRs for the review and release process you actually use. In our pipeline, human reading time is not the routine constraint. Keep commits small, traceable and intact, so a single change can be found and cherry-picked with its dependencies. Split PRs when risk, integration or review quality calls for it.
- Remove duplicate review without giving up early defect detection. Reuse context where you can, check each change before merge, and verify the complete outcome at acceptance.
- Write down what a pipeline change should move before you ship it, then check it a week later.
- Keep a board where humans work. A team with human reviewers may still want one for the work people touch. The case against it here is narrow: agent work that moves faster than anyone reads it.
At team scale
We have no data from a multi-person team. We have not checked whether GitHub’s API limits for Projects would throttle many pipelines writing to one organization’s boards. Milestones use the REST API, which has different limits. We have not tested either.
Method
- Source: local Claude Code transcripts for the three products, including worktree sessions. Claude Code keeps 30 days of transcripts, so the board side covers its last 18 days and the Milestones side its first 11. Codex review tokens are not included in either column.
- We ran the token analysis on October 11. Claude Code has since deleted the oldest board-era transcripts, so the board-side token figures can no longer be recomputed. A rerun on October 20 reproduced the Milestones side.
- Tokens per response are input plus cache write plus cache read plus output, deduplicated by message id. Cache reads make up most of every total and are counted in full.
- Context loading is estimated as the first response’s context in each session, counted again on every response. This proxy does not reconstruct what survives compaction or how the context changes. It does not measure redundant or avoidable work directly.
- Board calls are shell commands against the board helpers or the Projects API. Package queue and milestone calls go to the package queue or the milestones REST API. An issue read fetches one issue. A call’s estimated tokens are its result (characters / 3.5), written once and read again on every later response in the session, plus its share of the issuing response’s output tokens. This allocation assumes the result stays in context; truncation and compaction can change that. Work is the residual after these estimates, not a separately measured category.
- Tickets: sessions are tied to an issue or package through the dispatch prompt, the branch name, the worktree path or the PR they review. That ties 40 to 50% of all tokens to a ticket. The rest is runner, planning and leadership sessions, which the per-ticket numbers leave out. A ticket’s size is the lines changed in its merged PRs. PRs over 10,000 lines (generated data) are left out of the fit.
- Estimated size-independent part: the intercept of an ordinary least-squares fit of a ticket’s tokens against its lines changed. This is an observational model, not a measurement of startup work. The analysis does not report confidence intervals or adjust for task type or complexity. The attributed 40 to 50% of tokens may not represent the rest.
- The board call table covers every project on the machine except the repo that holds the pipeline scripts. Tooling sessions are the sessions in that repo which edited a board file, counted in full.
- Board access without the helpers is modeled, not measured. Per operation it adds the extra turns a raw call needs (each one rereads the median 113,000-token turn of a session that used the board), the longer commands and the unfiltered results, and caps any single result at Claude Code’s 30,000-character shell output limit. The batched scenario comes to 1.3 times the estimated attribution for observed board calls and the separate-turn scenario to 7 times. Neither scenario has been shown to be typical. Board size is the least certain input: the boards are deleted, so the number of cards per board is estimated from the number of issues per repo.
- PR size: additions plus deletions of merged PRs. PR type: the conventional-commit prefix of the merged PR title, for September 23 to 29 (Projects) and September 30 to October 6 (Milestones). Package size: the merged PRs whose body or branch references the package issue. Issue outcomes: the last comment on each closed issue.
- Days are UTC.